Tag: chrome extension

  • Kendo Email Finder Chrome Extension: A Practical Guide

    Kendo Email Finder Chrome Extension: A Practical Guide

    You've found a promising prospect on LinkedIn, opened the company website, checked the contact page, and still haven't found a usable email address. After repeating that process across several accounts, the true cost becomes obvious: manual research consumes selling time, while rushed copying creates duplicates, misspellings, and incomplete CRM records. A browser extension can remove much of that friction, but installation is only the starting point.

    The practical questions are harder. What can the extension access? Where do discovered addresses go? Does a found address belong to the person you want to contact, and can you lawfully use it for outreach? This guide examines the Kendo email finder Chrome extension through that operational lens, including workflow design, permissions, verification, data hygiene, and responsible activation.

    What Is the Kendo Email Finder Chrome Extension

    A sales representative researching a target account usually moves between several tabs. LinkedIn supplies the person and role, the company website confirms the business, Google surfaces additional pages, and the CRM becomes the place where everything must eventually be recorded. The weak point is the handoff. Copying an address from one tab to another feels harmless, but it creates opportunities for transcription errors and inconsistent notes.

    The Kendo email finder Chrome extension is designed to sit inside that browser workflow. Rather than making the user leave the active page for every lookup, it can help identify business contact details while the user researches profiles, websites, or search results. The useful principle is simple: reduce the number of manual transitions between discovery and record creation.

    That doesn't mean every detected address is correct or appropriate for outreach. A browser tool can surface a pattern, an address displayed on a page, or a possible match. It can't automatically establish that the mailbox is active, that the person still holds the role, or that the user has a lawful basis for contacting them. A clear distinction between discovery, verification, and activation prevents a fast tool from becoming a fast way to create bad data.

    For readers evaluating the category rather than one product, this overview of email finders provides useful terminology for separating email discovery from broader enrichment. In day-to-day operations, the extension is most valuable when it supports a defined process: identify a relevant contact, capture the source URL, check the result, deduplicate the record, and only then decide whether it belongs in an outreach sequence.

    Installing and Configuring Your Extension

    Start with the Chrome Web Store listing, not a download link sent through an unfamiliar message. Check the publisher, requested permissions, privacy disclosures, and recent user feedback before selecting Add to Chrome. The store's user metric reflects installations, not necessarily active usage, as explained in Chrome's documentation on extension metrics, so installation volume alone shouldn't determine whether a tool deserves access to your browsing environment.
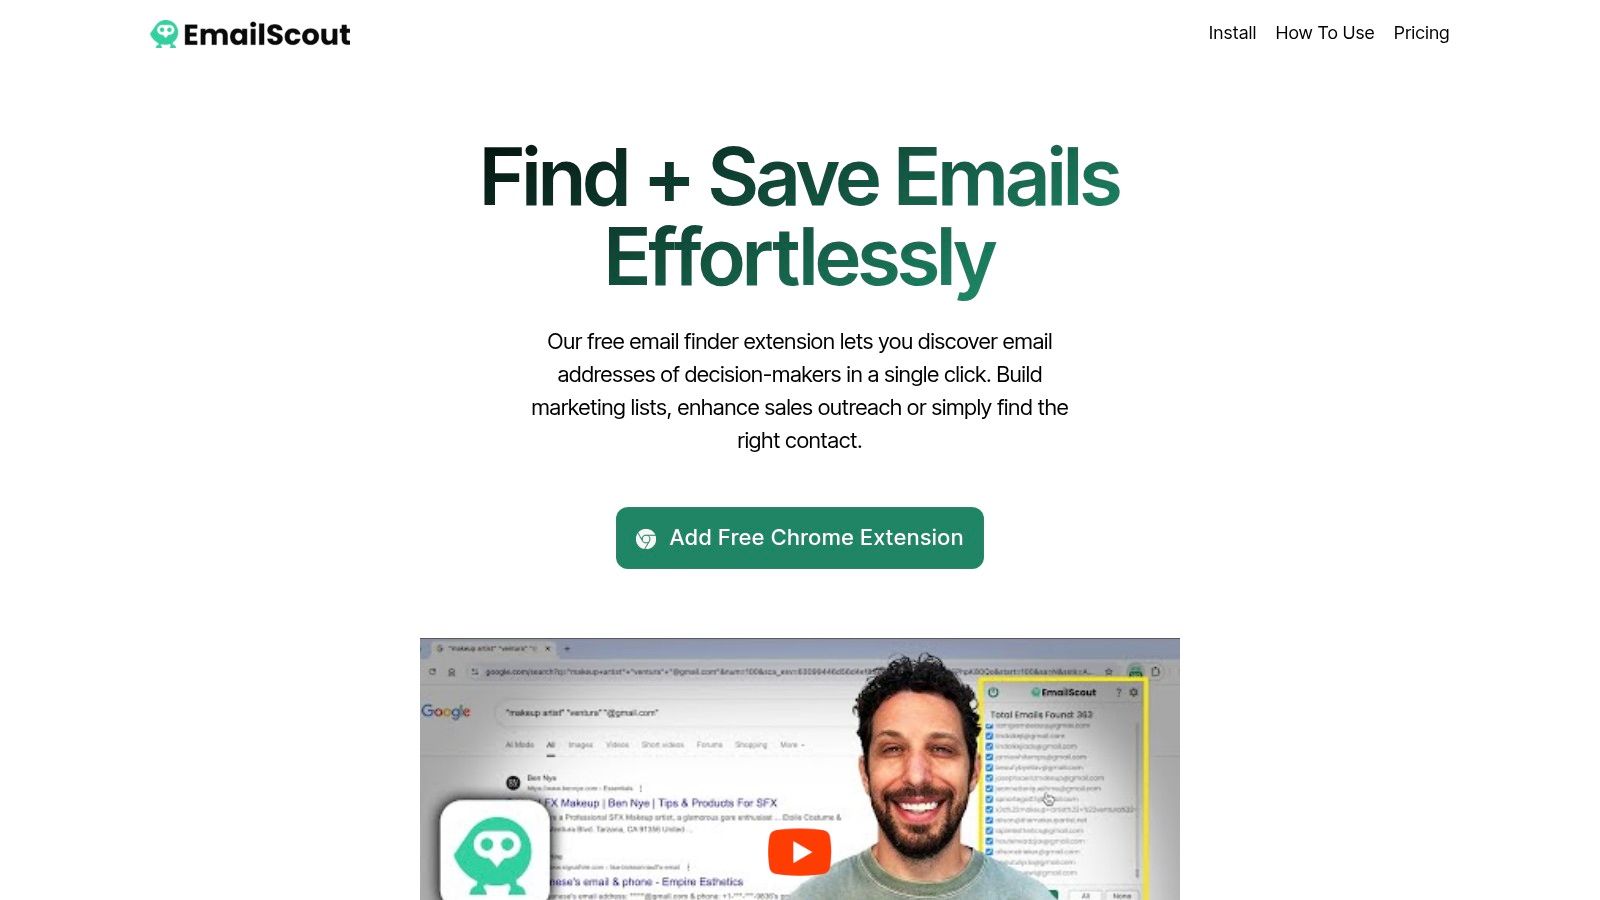
    Screenshot from https://emailscout.io

    After installation, pin the extension from Chrome's extensions menu so the control remains visible during research. Sign in or create the required account, then review the initial settings before opening prospecting pages. If the product offers choices for automatic saving, export format, or connected destinations, select the narrowest configuration that matches your workflow.

    Configure access before collecting data

    Chrome distinguishes API permissions, optional permissions, and host permissions. Host permissions determine which domains the extension can access, while content-script match patterns determine where code may be injected. Use the Chrome permissions guide to understand what each request means, then avoid granting broad access to every website when the workflow only requires a small set of approved domains.

    A sensible first-run checklist looks like this:

    1. Review each domain request. Allow only the pages needed for current prospecting.
    2. Test one approved profile and one company page. Confirm that the extension responds where expected.
    3. Inspect the output before enabling AutoSave. Make sure the source URL, name, company, and result are captured in a useful format.
    4. Set an export destination. Decide whether CSV or TXT is appropriate before the first batch.
    5. Document the process. Tell team members what they may collect and which fields must be reviewed.

    Use this guide to lead-generation Chrome extensions as a reference point when comparing browser-based workflows. A short permission review at the beginning is more efficient than investigating unexplained data collection after a campaign has already launched.

    For a visual walkthrough of the browser workflow, use the following demonstration after reviewing the settings above.

    Core Features That Power Your Outreach

    The value of an email-finding extension comes from how well it fits the work around the lookup. A result that stays in a browser popup still creates administrative work. A result that carries its source, confidence status, and review history into the next step becomes a usable sales record.
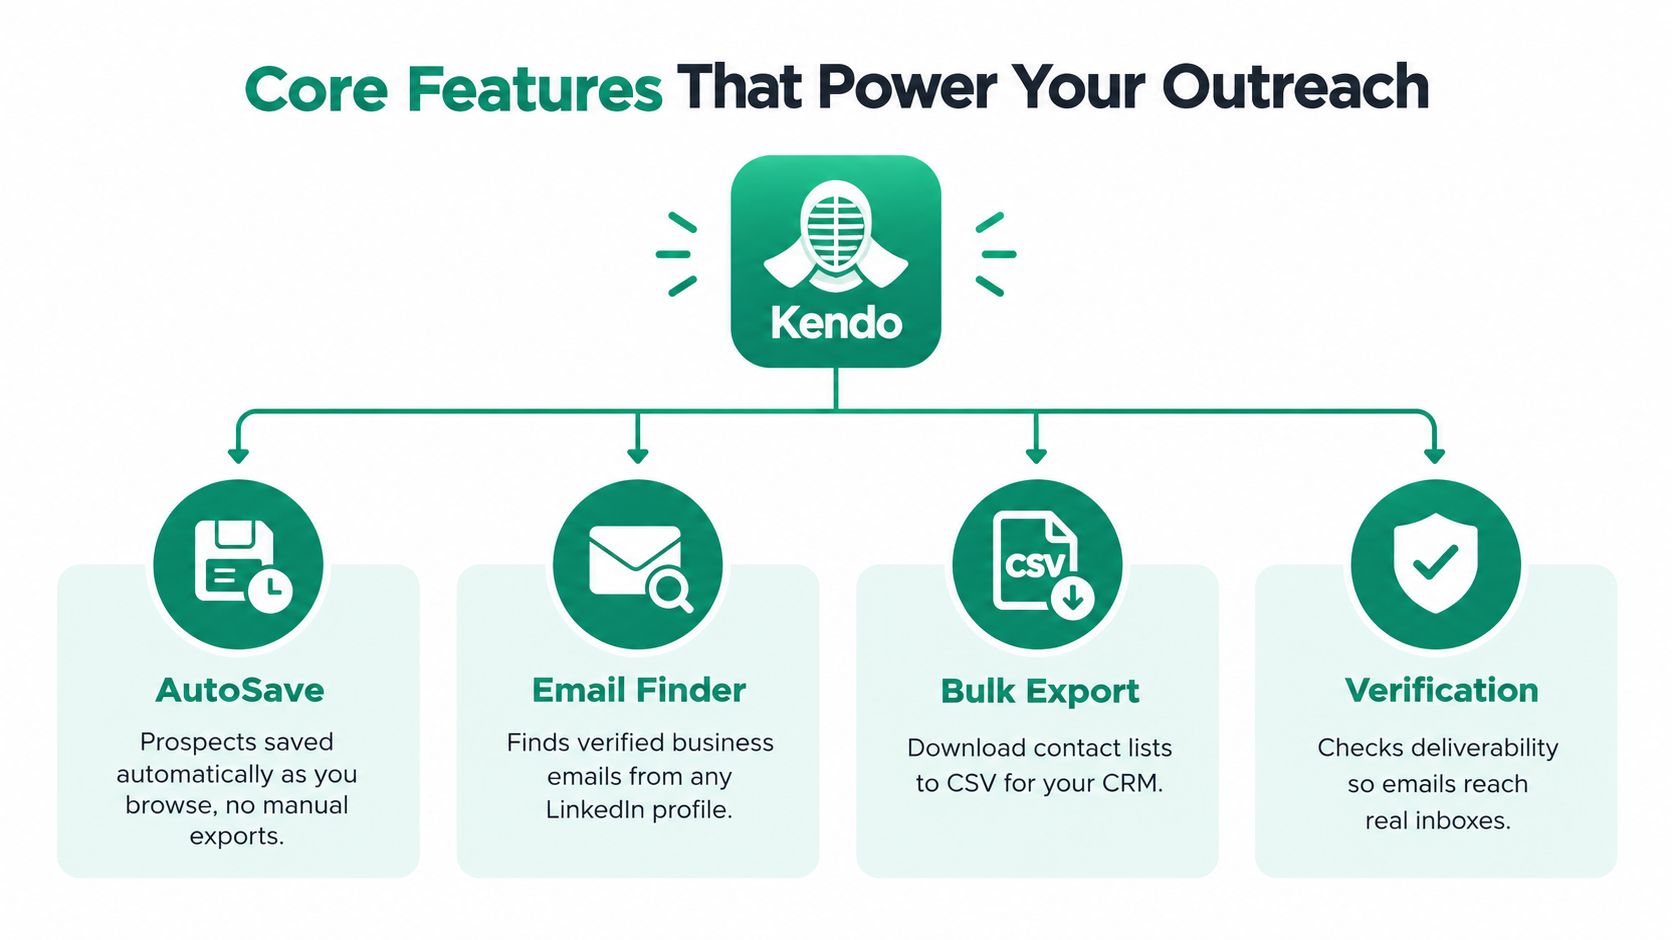
    An infographic showing the four core features of Kendo email finder including AutoSave, Email Finder, Bulk Export, and Verification.

    AutoSave should support review, not replace it

    AutoSave can capture addresses as a representative browses, which is helpful during account research. It reduces repeated copying and lets the user stay focused on the page. The operational risk is silent accumulation. If every discovered address enters a shared list automatically, the database can fill with duplicates, generic mailboxes, outdated roles, and records collected for the wrong client.

    Configure AutoSave with a review stage wherever possible. Store the source URL, collection date, target company, and person name alongside the address. Those fields make later investigation possible when a colleague asks where a record came from or why it was added.

    URL Explorer is useful for account-level research

    URL Explorer is suited to a different job. Instead of waiting for a result on one page, a researcher can submit a controlled set of company or profile URLs for extraction. This can speed up research across a defined account list, but it also increases the need for scope control. Batch processing should never become an excuse to collect every address from unrelated pages.

    Create batches by campaign, client, or account segment. Review the output for duplicates and role accounts before sending it to a CRM or sequencer. The extension's network requests also need to be explicitly allowed by its permissions, and Chrome recommends limiting access to capabilities that are essential to the feature, as described in its user privacy and security guidance.

    Export is a handoff, not a quality check

    CSV and TXT exports are convenient because they work with many sales systems. They don't validate the records. Before import, normalize capitalization, remove duplicate addresses, map the company and contact fields, and preserve the original source. A clean export should make it obvious which records are ready for verification and which still need review.

    The best workflow treats the extension as the collection layer. Validation, suppression checks, CRM matching, and campaign eligibility belong in the next stages. That division keeps speed from being confused with accuracy.

    Privacy and Data Governance Considerations

    “Free” describes a price, not a security posture. A browser extension may interact with page content, browsing activity, account information, and contact records, depending on its permissions and architecture. Before granting access, a sales operations manager should be able to answer what the extension reads, what it sends to a server, how long the data is retained, and how an administrator or user can delete it.

    Security research reported 287 Chrome extensions allegedly exfiltrating browsing-history data, affecting an estimated 37.4 million installations, according to The Register's report on the research. That finding doesn't establish that every email-finder extension behaves that way. It does show why users should evaluate permissions and data flows rather than treating a browser extension as a harmless button.

    Ask these questions before approval

    A procurement or security review should request direct answers to the following:

    • Page access: Can the extension run on every website, or only on user-approved domains?
    • Collection trigger: Does it collect data continuously, or only after a user action?
    • Storage location: Are addresses stored locally, on the vendor's servers, or in both places?
    • Retention: Can the user set a retention period and permanently delete collected records?
    • Sharing: Does the vendor disclose subprocessors, analytics use, or third-party enrichment?
    • Export control: Can administrators restrict downloads or audit who exported a list?
    • Client separation: Can an agency keep records for separate customers logically separated?

    Chrome specifically warns that extension storage isn't encrypted. A locally stored contact list should therefore not be treated as secure because it never appears in a visible CRM. If AutoSave transmits data to a backend, the organization also needs to understand the transport, access controls, deletion process, and contractual terms.

    Practical rule: Grant the smallest permission set that supports the current task. Add a domain only when the workflow requires it, and remove access when the project ends.

    For European contacts, privacy review also has a legal dimension. The European Commission's GDPR guidance explains that automated processing of personal data falls within the GDPR, and that personal data includes information relating to an identified or identifiable living person. An address doesn't stop being personal data because it was found publicly or because it was pseudonymized.

    A defensible process records provenance, limits collection to a stated purpose, protects exports, honors deletion requests, and gives users a way to object where required. Those controls matter more than a broad promise of unlimited discovery.

    From Discovery to Compliant Outreach

    An address can be syntactically correct and still be unusable. It may belong to a former employee, route to a catch-all domain, represent a shared role account, or fail because the mailbox no longer accepts messages. It may also be publicly visible without giving the collector permission to use it for a particular marketing purpose.

    Treat finding and validation as separate workflow events. Discovery answers, “What address might be associated with this person or company?” Validation asks whether the address appears technically reachable and how confident the system is. Compliance asks a different question, “Can this organization process the data and send this communication under the rules that apply?”

    Build confidence into the record

    A useful record should contain more than an email string. Capture:

    • Source URL: Where the address was found.
    • Discovery time: When the result was collected.
    • Confidence state: For example, domain valid, mailbox likely, catch-all, or undeliverable.
    • Verification time: When technical checks were last performed.
    • Contact context: Person, role, company, and campaign purpose.
    • Suppression status: Whether the address must be excluded from outreach.

    Server-side verification may examine domain mail configuration and controlled SMTP-level signals without sending an unsolicited message. Even then, results can be inconclusive. Catch-all behavior, temporary failures, role accounts, recycled mailboxes, and anti-enumeration controls all limit what verification can prove.
    A woman working on a laptop at a desk while taking notes in a spiral notebook.

    Public availability isn't permission

    A professional address displayed on a website may support a relevant business conversation, but public visibility isn't a universal permission slip. The European Commission specifically identifies promotional email as an activity that must comply with applicable data-protection and ePrivacy rules. The GDPR can also apply to organizations outside the EU when they offer services to people in the EU or monitor their behavior.

    Keep the first activation narrow. Exclude generic addresses such as info@ and support@ when the campaign requires an individual decision-maker, and don't treat a successful lookup as consent. Include a clear objection or unsubscribe path appropriate to the communication, maintain a suppression list, and stop future messages when a recipient objects.

    Gmail deliverability rules add a separate operational constraint. Google defines a bulk sender as one sending close to 5,000 messages or more to personal Gmail accounts within 24 hours, and says enforcement for non-compliant traffic is being ramped up from November 2025, as stated in Google's sender guidelines. The lesson is broader than that threshold: list growth should not outrun authentication, bounce monitoring, sender reputation, or unsubscribe handling.

    A responsible prospecting list is therefore not the largest list. It's a reviewed set of relevant contacts with traceable sources, explicit confidence states, suppression controls, and a clear reason for outreach.

    Comparing Kendo with EmailScout Alternatives

    A fair comparison starts with the job to be done, not the number of buttons in a popup. Kendo is positioned as a browser-first email discovery tool for users who want to work from LinkedIn and other web pages. Other products may focus on domain search, large databases, CRM enrichment, phone data, or outreach automation.

    The right choice depends on where the bottleneck occurs. If representatives already know their target accounts and need a quick lookup while browsing, a lightweight extension can be practical. If the team needs account discovery, enrichment, validation, ownership rules, and reporting, a standalone platform or CRM-connected system may justify more setup.
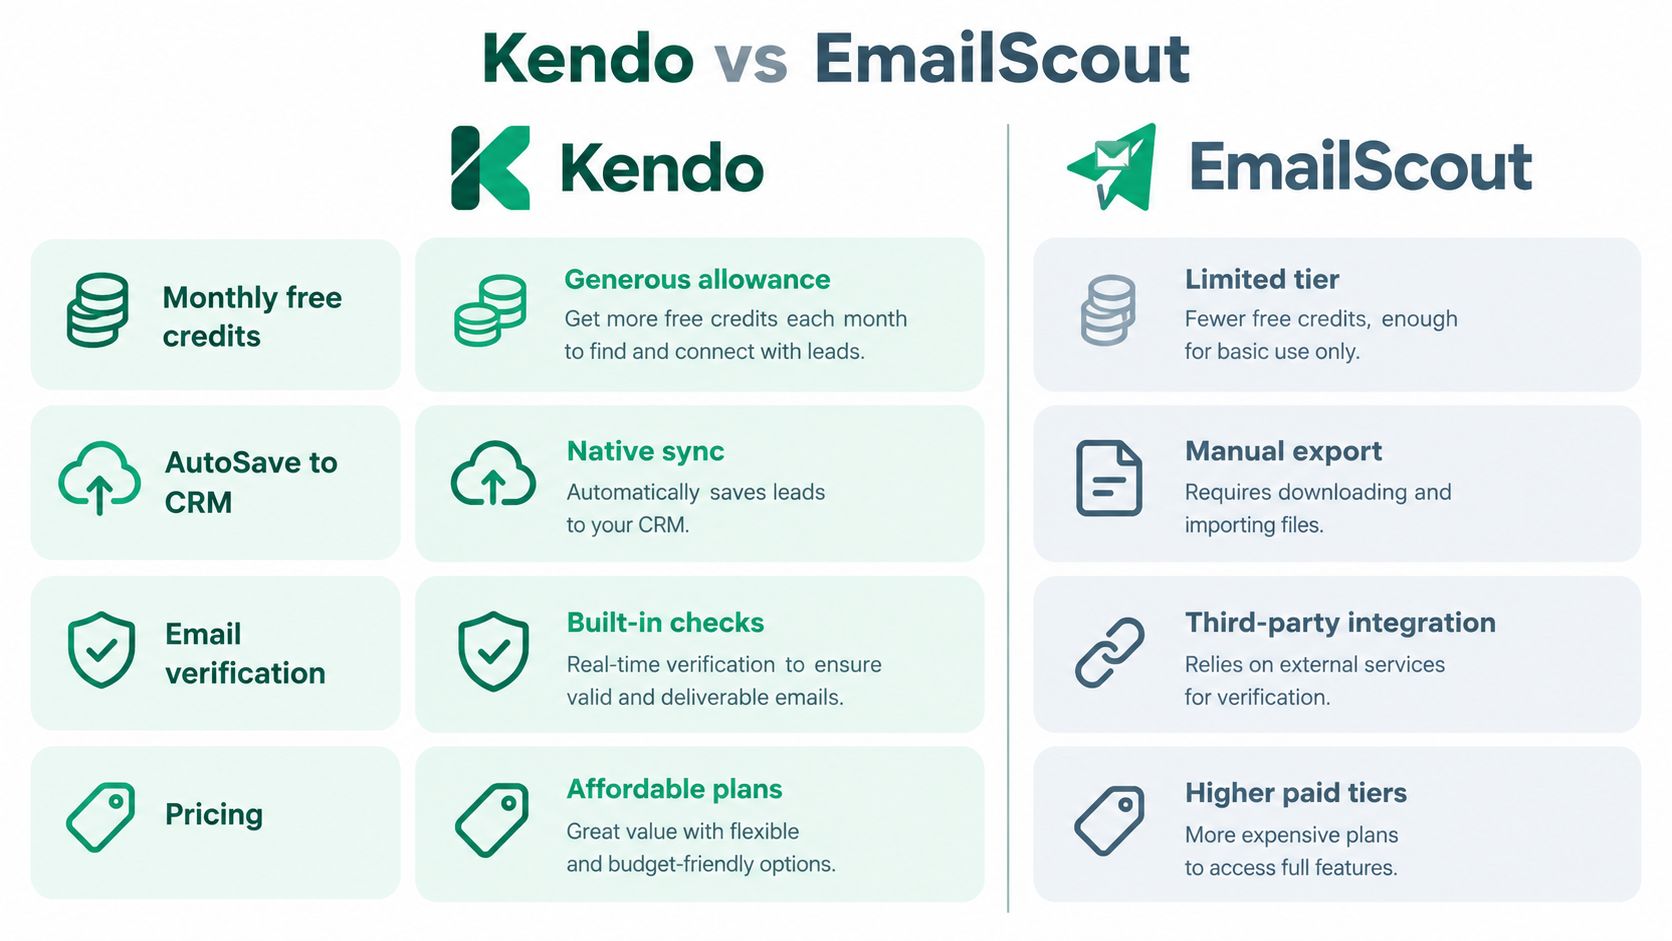
    A comparison chart showing features of Kendo versus EmailScout, highlighting Kendo's advantages for sales and lead generation.

    Compare the workflow, not just the feature list

    Evaluation area Kendo-style browser workflow Broader alternative workflow
    Starting point A profile, company page, or search result A domain, uploaded list, database, or CRM record
    Main advantage Fast research with fewer tab changes More structured enrichment and list management
    Main risk Automatic collection can create unreviewed records More integrations can increase data-sharing complexity
    Best control Narrow permissions and source capture Field mapping, validation states, and audit trails
    Operational question Can the result be reviewed before export? Can the team govern the full record lifecycle?

    For a small team, a browser extension may be enough if someone owns deduplication and verification. For a larger sales operation, native CRM sync can reduce manual imports, but it should still preserve provenance and prevent duplicate ownership. A tool that exports quickly isn't automatically better than one that exports less often with stronger controls.

    Teams comparing products can use this email-finder software guide to frame the decision around discovery method, export needs, verification, and governance. Don't accept a product claim about “verified” at face value. Ask what the status means, when it was assigned, whether catch-all results are separated, and how the system handles failed checks.

    Price also needs context. A low-cost tool can become expensive when representatives spend time cleaning exports or when poor records create bounces. A higher-priced platform can be wasteful if the team only needs occasional domain lookups. Run a controlled test with representative accounts, measure the manual cleanup required, and review the permission model before committing.

    Troubleshooting Common Issues

    When an extension fails to find an address, start with the page rather than repeatedly clicking the button. Some pages load contact details dynamically, some restrict content behind an account, and some do not expose an address. A missing result isn't proof that the person has no business email.

    Use this sequence:

    1. Confirm the domain is approved. Check the extension's site access settings and avoid granting broad access as a quick fix.
    2. Refresh the page. A recently opened tab may not have loaded the content script correctly.
    3. Test a known company page. This separates a page-specific issue from an account or extension problem.
    4. Temporarily review privacy tools. Ad blockers and script controls can interfere, but don't disable them permanently without understanding the trade-off.
    5. Check the account session. Sign out and back in if the extension shows stale status or refuses to save.
    6. Inspect the export fields. If the file downloads but appears empty, check the selected columns, file format, and browser download permissions.

    Keep Chrome and the extension current, then clear cached site data only after preserving any records that haven't been exported. If a result is visible but the extension doesn't capture it, record the source manually and report the page pattern to the vendor. Avoid repeated automated attempts on restricted sites, since aggressive behavior can create account or access problems.

    Best Practices for Effective Prospecting

    Good prospecting begins before the lookup. Define the account criteria, target role, geography, and campaign purpose first. Then research only the pages that can support those criteria, capture the source, and review each result before it enters a sequence.

    A sustainable operating rhythm looks like this:

    • Start with relevance. A smaller set of well-matched decision-makers is more useful than a large collection of unrelated addresses.
    • Separate stages. Discovery, verification, CRM import, suppression checks, and sending should remain visible as different steps.
    • Preserve provenance. Keep the source URL and collection context so another operator can audit the record.
    • Protect client data. Agencies should separate workspaces, exports, and retention decisions by customer.
    • Monitor outcomes. Track bounces, objections, duplicates, and undeliverable results, then use those findings to refine collection rules.
    • Present a credible sender identity. A clear name, role, company, and guide to polished email signatures can make legitimate business correspondence easier for recipients to understand.

    The strongest Chrome workflow is not the one that collects the most addresses. It's the one that helps a team move from a relevant page to a traceable, reviewed, technically checked, and appropriately governed contact record without losing context.


    EmailScout offers browser-based email discovery from websites, Google results, LinkedIn profiles, and company pages, with options to copy or export collected addresses and use features such as AutoSave and URL Explorer. Visit EmailScout to evaluate whether its workflow fits your prospecting, data-hygiene, and review requirements.
  • How to Extract Emails from URL Without Losing Your Mind

    How to Extract Emails from URL Without Losing Your Mind

    You've got a prospect's URL, a campaign deadline, and a scraper that promises instant results. The page returns a list of addresses, so it looks like the job is done. Then the duplicates appear, generic inboxes crowd the export, JavaScript-rendered contacts stay invisible, and the first send produces enough bounces to damage the campaign.

    That's why experienced sales-ops teams treat extract emails from URL workflows as a data-quality operation first and a scraping operation second. Finding an address is only the first event in a chain that also includes validation, deduplication, relevance checks, suppression, and lawful outreach.

    Why Pulling Emails from a URL Is Harder Than It Looks

    A URL can return hundreds of apparent matches and still produce few usable contacts. The page may expose role accounts, duplicate CRM records, image filenames, or obfuscated placeholders. JavaScript-rendered team pages can hide contacts from a basic request, while click-to-reveal controls and deliberately planted addresses create more noise.

    A raw count does not measure contact quality. info@, press@, sales@, and support@ usually identify a department rather than the person responsible for a purchase. An address can also remain indexed after its owner leaves, so extraction has to be followed by identity checks and deliverability verification.

    A diagram illustrating why email extraction from a website URL often produces inconsistent and unreliable results.

    Where the simple approach breaks

    • Static HTML misses dynamic content: The initial document may load before scripts request contact data.
    • Visible text is not always an address: Symbols may be replaced with words, images, or delayed reveal elements.
    • Duplicates distort the list: One address can appear in a footer, privacy page, PDF, and team profile.
    • Public does not mean deliverable: Addresses may be stale, invalid, or inappropriate for unsolicited outreach.

    The operational risk is a list that looks full but performs poorly. Bounce rates, role-account volume, duplicate records, and outdated contacts all affect whether an extracted address belongs in an outreach sequence. Discovery answers where an address appears. Verification checks whether it is still valid, connected to the right person, and suitable for the intended campaign.

    Use the PeopleFinder email search guide for broader context on locating contact information, then apply your own permission, relevance, suppression, and validation checks before sending. EmailScout can help surface candidates from a URL, but the export is only an input to that process.

    Practical rule: A scraper gives you candidates. Your validation process decides whether they belong in an outreach sequence.

    Extracting Emails from a URL with EmailScout

    For a single prospect, start with the page most likely to contain useful context, usually the homepage, contact page, team page, or an executive profile. Open the page in the EmailScout extension, trigger the scan, and review the result categories before exporting anything.

    The useful distinction isn't just “found” versus “not found.” Separate the total discovered addresses from role-based addresses and unique addresses. That lets a rep decide whether a company is ready for pre-call research or whether the result needs a deeper crawl.

    Screenshot from https://emailscout.example/screenshot/url-explorer-bulk.png

    Use a single URL for focused research

    A homepage scan works well before a discovery call. You can identify a general business address, compare it with contacts already in the CRM, and inspect linked social profiles for names and job titles. Where matching LinkedIn URLs are available, social-profile enrichment can add useful identity context to an address that would otherwise be just a string in a spreadsheet.

    Autosave matters during this stage. Saving results automatically to CSV or Google Sheets reduces the chance that a closed tab, browser crash, or interrupted session wipes out work. The output still needs review, but the process no longer depends on keeping one browser window open.

    For teams documenting broader buyer-data workflows, this buyer data capture toolkit provides useful surrounding context. The same principle applies here: preserve the source and context alongside the contact record, rather than exporting an address with no explanation of where it came from.

    Use URL Explorer when the work is repetitive

    Bulk work belongs in a queue, not in a sequence of manually opened tabs. Add a set of prospect domains to URL Explorer, choose a crawl depth, set a result cap, and let the job process in the background. A homepage-only run is appropriate for quick qualification. A shallow crawl is better when contact or team pages are linked from the main site. A full-site run should be reserved for cases where the extra pages have a clear business purpose.

    The practical advantage is control. A trade-show list can run as one batch, while a stale segment can be rechecked without forcing a rep to monitor every page. Results can stream into the working dataset as they arrive, so the team can inspect early output and stop a noisy run before it consumes more time.

    Don't treat the tool's count as a campaign-ready total. Tag source URL, page type, role status, and review state immediately. Extraction is useful when it shortens research. It becomes expensive when it hides the cleanup still waiting afterward.

    Quick Wins Using Your Browser and Devtools

    You don't need an extension for every extraction session. On a locked-down work machine, the browser itself can reveal what the server delivered and what the page loaded later.

    Start with View Source using Ctrl+U on Windows or Cmd+U on macOS. Search for mailto: first, then use a regex-flavored pattern such as [w.+-]+@[w-]+.[w.-]+ to locate address-shaped strings in the returned HTML. This catches visible addresses and links that a basic page reader may overlook, but it won't reveal data that the browser fetches only after scripts execute.

    Inspect the loaded document

    Open DevTools and switch to the Elements panel. Search the loaded DOM for mailto:. You can also run this in the Console:

    document.querySelectorAll('a[href^="mailto:"]')

    The selector returns links whose destination begins with mailto:. It's particularly useful for click-to-email elements and contact widgets that don't appear clearly in the original source.

    A contact form creates a different path. In the Network tab, reload the page and filter requests using terms such as contact, form, or email. Inspect requests that return HTML or submit data to an endpoint. You may learn how the form works, but a form with no visible email address isn't automatically an invitation to extract an underlying destination.

    A practical browser sequence

    Suppose a contact page visibly lists three marketing contacts. Run the checks in this order:

    1. Search the source: Look for normal address strings and mailto: links.
    2. Search the DOM: Check whether JavaScript added links after page load.
    3. Review Network requests: Confirm whether another request supplies the contact block.
    4. Record the page: Save the source URL and extraction date with each candidate.

    If the page shows names but no address, stop before guessing or probing private endpoints. For a more focused extension workflow, see this guide to mastering an email extractor Chrome extension. The browser path is excellent for small investigations, but repeated manual inspection doesn't scale cleanly.

    A Lightweight Code Snippet for Developers

    For a static page, a small Python script can collect address-shaped strings from the HTML and deduplicate them. It should fail loudly instead of pretending that an empty result proves the page contains no email.

    import re
    import sys
    import requests
    
    EMAIL_RE = re.compile(r"[w.+-]+@[w-]+.[w.-]+")
    
    def extract_emails(url):
        headers = {"User-Agent": "Mozilla/5.0"}
        response = requests.get(url, headers=headers, timeout=15)
        response.raise_for_status()
        found = EMAIL_RE.findall(response.text)
        return sorted({email.lower() for email in found})
    
    if __name__ == "__main__":
        if len(sys.argv) != 2:
            raise SystemExit("Usage: python extract.py ")
    
        try:
            for email in extract_emails(sys.argv[1]):
                print(email)
        except requests.RequestException as error:
            raise SystemExit(f"Request failed: {error}")
    

    The regex is intentionally simple. It finds conventional address strings in the response body, normalizes casing, and removes duplicates. It won't solve JavaScript-rendered pages, image-based addresses, word substitutions such as “at” and “dot,” contact forms, or pages protected by a challenge. It also won't tell you whether a mailbox exists or whether the address is appropriate for outreach.

    The Node.js equivalent

    Node's built-in fetch provides the same basic approach:

    const EMAIL_RE = /[w.+-]+@[w-]+.[w.-]+/g;
    
    async function extractEmails(url) {
      const response = await fetch(url, {
        headers: { "user-agent": "Mozilla/5.0" }
      });
    
      if (!response.ok) {
        throw new Error(`Request failed with ${response.status}`);
      }
    
      const html = await response.text();
      return [...new Set(
        (html.match(EMAIL_RE) || []).map(email => email.toLowerCase())
      )];
    }
    
    const url = process.argv[2];
    
    if (!url) {
      console.error("Usage: node extract.js ");
      process.exit(1);
    }
    
    extractEmails(url)
      .then(emails => emails.forEach(console.log))
      .catch(error => {
        console.error(error.message);
        process.exit(1);
      });
    

    Use a browser automation framework such as Playwright when the page visibly shows contacts but the HTTP response returns none. That usually means the data lives in a client-rendered DOM or behind a script-controlled loader. Even then, respect access controls, rate limits, and the site's terms. A headless browser can render more content, but it can't turn questionable collection into responsible collection.

    Verifying and Cleaning Your Extracted List

    Verification is the control that separates a usable prospect list from a bounce-heavy export. An address appearing on a page proves only that text matched an email pattern. It does not prove the mailbox exists, belongs to the right company, or fits your outreach.

    The available evidence is sobering. Testing cited in an industry account found that, among 553 emails identified by lookup tools, only 38% were correct, 34% were wrong, and 28% were not found. The same account reported that 59% of the wrong addresses never bounced, so delivery alone cannot expose every bad record. Extraction without verification creates false confidence.

    A diagram illustrating the four-step email verification process to ensure high deliverability and reduce bounce rates.

    First pass for list hygiene

    Start with deterministic cleanup before paying for deeper checks:

    • Normalize: Convert addresses to a consistent case and remove surrounding spaces.
    • Deduplicate: Compare each normalized address with the CRM and current campaign files.
    • Classify roles: Flag noreply@, admin@, info@, sales@, and similar shared inboxes for separate review.
    • Preserve provenance: Store the source URL, page path, and extraction date beside each address.
    • Suppress known risks: Remove prior opt-outs, complaints, invalid records, and addresses outside the campaign's approved audience.

    This pass is inexpensive and catches errors a verifier may miss, including an address tied to the wrong company or a generic mailbox that does not suit the campaign.

    Second pass for deliverability

    Use a validation service or internal workflow to check syntax, domain health, and mailbox signals. MX lookups can show whether a domain is configured to receive mail. Paid verification APIs such as NeverBounce or ZeroBounce can add classifications, but they still require review. Treat catch-all domains cautiously because they may accept mail for addresses that are not real individual inboxes.

    Use the email validation guide as a practical checklist. A verified address can still be irrelevant, unwanted, or legally restricted.

    A smaller list with documented provenance and clear suppression rules is more valuable than a large list nobody trusts.

    Scaling to Multiple URLs Without Drowning in Noise

    More crawling doesn't automatically produce better sales data. A full-domain crawl often collects legal notices, footer addresses, PDFs, old staff pages, and repeated shared inboxes alongside the contact information you need. The result is a larger file that requires more triage.

    Targeted multi-URL extraction is usually the better operating model. Build a shortlist of likely paths, such as /contact, /about, /team, and /press, then run those URLs rather than treating every discoverable page as equally valuable.

    Metric Targeted, 10 to 25 URLs Blanket Crawl
    Primary purpose Find relevant contact context Discover everything available
    Typical review burden Focused and easier to audit High, with repeated and irrelevant pages
    Duplicate risk Manageable with URL and email deduplication Elevated across footers, PDFs, and archives
    Best use Prospecting and account research Site inventory or controlled research
    Main trade-off May miss an unusual contact path Produces breadth at the cost of signal

    The source material for this workflow identifies 10 to 25 URLs per domain per session and a 2 to 3 second delay between requests as practical operating guidance. Treat those figures as a cautious configuration reference, not a universal rule. Site policies, infrastructure, and authorization still determine what responsible crawling looks like.

    Quality beats volume: A targeted record earns its place by connecting an address to a relevant person, team, or business function.

    Legal and Ethical Lines You Should Not Cross

    A public email address isn't a universal license to send marketing messages. The legal outcome depends on the person's location, the sender's location, the message, the collection method, and the applicable rules. CAN-SPAM, GDPR Article 14, and Canada's CASL each create different requirements, so global teams should involve qualified legal counsel before launching a scaled workflow.

    Use a pre-send review that joins extraction with compliance:

    1. Confirm context: Record where the address appeared and whether the page presented it as a business contact.
    2. Assess the mailbox: Treat shared addresses such as info@, sales@, and press@ separately from named professional contacts.
    3. Apply transparency: If personal data is involved, determine what notice and lawful basis the relevant jurisdiction requires.
    4. Honor suppression: Maintain an opt-out list and stop future outreach to suppressed addresses. CAN-SPAM requires opt-out requests to be honored within 10 business days, as described in the plan's legal guidance.
    5. Keep an audit trail: Store the source URL, extraction date, validation result, campaign, and suppression status.

    The email scraping compliance overview can help teams frame the operational questions, but it isn't a substitute for jurisdiction-specific advice. A targeted message that references a prospect's public business context is materially different from an indiscriminate blast to a scraped database. Both still require careful review, and neither should bypass consent, transparency, or opt-out duties.

    A visual guide summarizing three main email marketing regulations: CAN-SPAM, GDPR Article 14, and CASL compliance requirements.

    Start with a controlled pilot of 200 contacts, document the decision criteria, and make suppression part of the workflow before the first send. That approach gives sales and marketing a way to learn from the data without turning an extraction experiment into an uncontrolled mailing operation.


    EmailScout can scan a page for public email addresses, save findings through AutoSave, and use URL Explorer for multi-URL discovery, while your team handles validation, relevance, and compliance. Visit EmailScout to test a URL-based workflow and build a cleaner process before expanding outreach.

  • Find That Email Extension: A 2026 Guide to Unlimited Leads

    Find That Email Extension: A 2026 Guide to Unlimited Leads

    You've got the right account. You've identified the right person. You even know why your offer matters to their team.

    Then outreach stalls because the one thing you need, a working business email, isn't obvious anywhere.

    That's where the find that email extension category became so popular with sales reps, founders, recruiters, and marketers. The promise is simple: open a profile, click an icon, get the contact. It is often messier in practice. Some extensions are useful for one-off lookups. Some are decent for list building. A lot of them look free until you hit a wall, burn through credits, or realize the address you found still needs validation before it's safe to use.

    Used well, these tools can speed up prospecting. Used badly, they waste time and create bounce problems. The difference usually comes down to workflow, verification, and knowing which limits matter before you build your process around them.

    The Search for the Right Contact in a Digital Haystack

    The most common prospecting failure isn't a bad email sequence. It's never getting to the inbox in the first place.

    A rep finds a VP on LinkedIn, sends a connection request, maybe follows up with InMail, and waits. The buyer is busy, the message gets buried, and the opportunity goes cold. That's why browser-based email finders became part of the standard outbound stack. They remove the delay between identifying a contact and starting direct outreach.

    The frustration starts when “free” doesn't mean usable at working volume. According to analysis summarized from reviews and forum complaints, 70% of comments on some forums mention quota burnout within days, and only 15% of users are retained after free trials because they hit unexpected paywalls (review analysis on the Chrome Web Store listing). If you prospect every day, that matters more than a slick interface.

    What usually breaks the workflow

    A lot of reps don't fail because they picked the wrong prospect. They fail because their tool forces them to ration searches.

    • Credit anxiety: You stop checking secondary contacts because every lookup feels expensive.
    • Trial trap: The extension works during testing, then locks the useful features when real prospecting starts.
    • List paralysis: You avoid broad account coverage because you can't afford to enrich more than a handful of names.
    • Bad habits: Reps start guessing emails manually instead of using a repeatable process.

    Practical rule: If a tool makes you think harder about credits than contacts, it's shaping your outreach in the wrong direction.

    That's why many teams have started looking for an unlimited model instead of another “free” extension with a hidden ceiling. The appeal isn't just cost. It's momentum. You can check the first contact, the backup contact, and the department head without debating whether the search is worth spending.

    For teams building a broader outbound engine, this matters as much as message quality. If you're refining your list-building process alongside outreach, these strategies for B2B growth give useful context on how contact discovery fits into the bigger pipeline, not just the first click.

    What actually works

    The best workflow is simple. Identify the account, map likely decision-makers, pull direct business emails, verify what you can, and move into outreach while the research is still fresh. Anything that interrupts that sequence lowers output.

    That's why a find that email extension should be judged on one question first. Can you keep prospecting without hitting a wall?

    How to Install and Set Up Your Email Finder in Minutes

    The setup should take less time than writing your first cold email.

    Most Chrome extensions in this category are straightforward to install. You find the official listing in the Chrome Web Store, click the install button, approve the browser permissions, and the icon appears near your address bar. After that, the only habit that matters is pinning it so you can launch it without hunting through the extension menu.

    A hand pointing at the install button on a browser screen for the ProjectBridge extension software.

    What to check before you install

    A lot of users skip this part and regret it later. Before adding any find that email extension, check the listing carefully.

    Look for the official publisher name, a clear description of what the extension does, and whether the tool is built around credits or open usage. That pricing model matters early. FindThatLead uses a credit-based system where one credit is consumed per contact found, which is common across the category and can force reps to be selective about lookups (FindThatLead Chrome extension details).

    That doesn't make credit-based tools bad. It just means you should know the trade-off before the extension becomes part of your daily prospecting routine.

    The small setup move that saves time

    Pin the extension to your toolbar immediately.

    That sounds minor, but it changes how often you'll use it. If the icon is visible while you browse LinkedIn, company sites, and search results, checking a contact becomes automatic. If it's hidden behind the Chrome extension menu, you'll use it less and break your research flow.

    A clean setup usually looks like this:

    1. Install the extension from the official listing.
    2. Pin it to Chrome so it stays visible.
    3. Log in once so your searches and saved contacts sync properly.
    4. Open a prospect page right away to confirm the extension loads.

    For users comparing options, it also helps to review a dedicated product page instead of relying only on store screenshots. This email extractor Chrome extension overview is useful if you want to understand the kind of workflow modern prospecting extensions are built for before committing to one.

    The best setup is the one that gets you from install to first prospect without friction.

    If your extension asks for too much effort upfront, expect that friction to show up every day afterward too.

    Finding Your First Prospect Email with EmailScout

    The first successful lookup is usually what makes the category click.

    You open a prospect's LinkedIn profile. Maybe it's a marketing director at a target account, maybe a founder at a startup you've been tracking. You click the pinned extension icon, wait a moment, and the tool returns the most useful thing on the page: a business email you can use for outreach.

    A person holding a laptop displaying a LinkedIn profile with an email address found on the screen.

    A good extension doesn't just spit out one field. It often gives surrounding context too, such as job title and company information, which helps when you're writing the first message. That context matters because the strongest cold emails don't sound like they were sent to a database row. They sound like they were written for a person with a role and a business problem.

    What you'll usually see in the pop-up

    When a lookup works, the interface is normally compact and practical. You click once, and the extension displays the contact details tied to that person or company.

    What matters isn't flashy design. It's whether the result helps you act immediately. Can you copy the address, confirm the company, and move to outreach without opening three more tabs?

    Here's the part many users miss. Not every result is equal, and the better tools are honest about that.

    Some extensions use confidence scores to signal whether an email is strongly supported or more tentative. One prominent extension in this space has over 12,000 user reviews and displays likely results in different colors, such as green for stronger confidence and orange for unverified cases, which helps set expectations instead of pretending every result is equally certain (Chrome Web Store listing for Find That Email).

    A transparent tool is easier to trust than one that labels every guessed address as a win.

    That matters during prospecting because false certainty is expensive. A guessed address can still be useful, but you should treat it differently from a strongly supported one.

    A practical first-use routine

    If you're trying a find that email extension for the first time, don't start with a giant list. Start with a single target account and work one profile at a time.

    Use this quick routine:

    • Open one decision-maker profile: Pick someone you'd email today if you had the address.
    • Run the lookup: Check whether the extension returns an email plus role context.
    • Assess confidence: If the tool uses labels or colors, respect them.
    • Write the email immediately: Don't let found contacts pile up unused.

    A short visual walkthrough helps if you prefer seeing the motion of the process before doing it yourself.

    When no email appears

    This happens more often than beginners expect, and it doesn't always mean the extension failed.

    Sometimes the company's email pattern is hard to confirm. Sometimes the person has a weak public footprint. Sometimes the domain is correct but the role is too new to show up cleanly across the sources the tool checks. In those cases, smart prospectors don't stop at one person. They move laterally across the account and look for another relevant contact.

    That's the core value of a smooth extension workflow. It keeps you moving instead of getting stuck on a single missing address.

    Supercharge Prospecting with Advanced Features

    Finding one contact is useful. Building a working list while you browse is where the true advantage begins.

    Most reps underuse advanced extension features because they treat the tool like a lookup box instead of a prospecting system. That's a mistake. The strongest find that email extension workflow usually combines two modes: active searching when you need a specific person, and passive collection while you research accounts.

    AutoSave changes the pace

    AutoSave is one of those features that sounds small until you've used it for a week.

    As you move through profiles, company pages, and lead sources, the extension captures useful contact details without forcing you to manually copy everything into a spreadsheet. That matters because manual saving breaks concentration. Reps start skipping good contacts because the admin work feels annoying.

    Field note: The easier it is to save contacts during research, the more complete your account coverage becomes.

    This is especially helpful when you're mapping departments instead of chasing one champion. You can review multiple stakeholders in one sitting and keep your momentum.

    URL Explorer is where scale starts

    URL-based extraction is the feature power users usually want once they've outgrown one-by-one lookups.

    Instead of checking every profile individually, you work from a structured input such as company pages or a search results URL and let the extension pull available contact data from that source set. That's much closer to how real outbound teams operate when they're building campaigns by segment, title, or account list.

    The underlying mechanics are more advanced than many users realize. According to a benchmark summary from Prospeo, email finder tools rely on domain pattern recognition across 100+ formats, real-time API verification, and confidence scoring. The same source notes that top tools can achieve 95% accuracy on verified emails, while real-world usable rates after bounces are often closer to 70% (Prospeo benchmark overview).

    That gap is important. It explains why a list that looks strong at extraction time still needs sensible sending discipline afterward.

    What advanced users do differently

    They don't treat extracted lists as final truth. They treat them as working inputs for outreach.

    A stronger operating model looks like this:

    Workflow stage What good users do
    Research Build around target accounts and relevant titles
    Extraction Use URL-based collection for speed
    Review Separate stronger signals from weaker guesses
    Outreach Personalize by role, company, and trigger
    Cleanup Remove weak fits and recheck risky records

    If your team is comparing prospecting methods more broadly, this breakdown of B2B sales tactics for RevOps managers is worth reading because it frames list-building in the wider outbound versus inbound decision, not just the tool layer.

    Some users also compare extension options head to head before deciding which workflow suits them best. This Hunter email extension comparison is useful for seeing how different prospecting models align with daily outbound habits.

    The bottom line is simple. Advanced features aren't extras. They're what make an extension worth keeping open all day.

    Best Practices for Ethical and Effective Outreach

    A found email address is not permission to send lazy outreach.

    The sales teams that get the most from a find that email extension are usually the same teams that respect compliance, relevance, and timing. They know the job isn't “collect emails.” The job is “start qualified conversations without creating legal, platform, or deliverability problems.”

    An infographic titled Ethical Outreach Best Practices outlining six key strategies for professional and compliant email marketing.

    The platform risk is real

    Aggressive scraping habits have become a bigger issue, especially around LinkedIn. A source summarizing post-2025 enforcement reports notes that LinkedIn banned over 15 million accounts in 2025 for scraper violations, and a HubSpot survey found 60% of sales teams report churn from account bans (summary of enforcement trend).

    That should change how you prospect.

    The safest path is to avoid brittle, aggressive workflows that depend on heavy automated scraping behavior. Tools and methods centered on user-initiated actions and normal browsing patterns are easier to fold into a professional outreach process than anything that tries to brute-force extraction at platform-risking volume.

    What good outreach looks like

    Once you have the address, the next move matters more than the lookup.

    Use a simple standard:

    • Lead with relevance: Mention the role, company situation, or a concrete reason they're in your list.
    • Keep the first email narrow: One problem, one angle, one clear ask.
    • Sound like a person: If the message reads like mass automation, it will be treated like mass automation.
    • Make opt-out obvious: Professional outreach respects the recipient's choice.
    • Use timing well: A decent email sent at a sensible time beats a clever email sent thoughtlessly.

    Personalized outreach isn't about adding a first name token. It's about proving you understand why this person should care.

    That same principle applies to your public profile too. If prospects look you up after your email lands, your profile should support the message. This guide on how to optimize your LinkedIn headline is a practical reference because it helps align your outbound identity with the audience you're targeting.

    A clean first-touch framework

    Here's a structure that consistently beats generic pitching:

    1. Opening line
      Reference something real about the person, role, or company.
    2. Reason for contact
      Explain why you chose them specifically.
    3. Value statement
      State the outcome you help with, not a feature dump.
    4. Light ask
      Invite a reply, not a commitment to a full demo.

    This approach protects your reputation in two ways. It lowers the chance that your email gets ignored as obvious spam, and it keeps your process grounded in legitimate business context instead of indiscriminate list blasting.

    Ethical prospecting isn't slower. It's more durable.

    Troubleshooting and Privacy Considerations

    Most problems with a find that email extension are routine. They feel bigger than they are because they interrupt momentum.

    If the extension doesn't load, refresh the page first. If no email appears, check whether you're on a page with enough company or contact context for the tool to work from. If the contact seems perfect but the result is blank, move to another person at the same account instead of forcing the issue.

    Quick fixes that solve common problems

    A short checklist usually handles most day-to-day friction:

    • Extension not responding: Reload the browser tab and reopen the extension.
    • No contact found: Try a company page, another employee, or a different source page.
    • Results feel uncertain: Treat the address as tentative and validate before sending.
    • Toolbar icon missing: Re-pin the extension from Chrome's extension menu.
    • Saved contacts not appearing: Make sure you're logged into the correct account.

    Most prospecting issues are workflow issues, not tool failures.

    That mindset helps. You don't need every lookup to work. You need a process that keeps producing enough good contacts to sustain outreach.

    Privacy questions people should ask

    A lot of users ask whether email finder extensions are safe. That's the right question.

    The practical answer is this: the safety comes from how you use the tool, what permissions you grant, and whether you follow compliant outreach practices after you find the contact. Read the extension permissions before installation. Use business context, not indiscriminate scraping. Validate risky addresses before launching a sequence.

    Another smart habit is checking uncertain records with a dedicated verifier before they enter a campaign. This email address validation tool is the kind of extra step that helps reduce mistakes when a found address looks plausible but not fully reliable.

    What to remember

    Email finding tools are not magic. They're prospecting accelerators.

    They work best when you use them to support account research, not replace it. They're most valuable when they remove friction instead of adding new limits. And they're safest when they sit inside a disciplined outreach process that respects privacy, relevance, and platform rules.


    If you want an easier way to prospect without getting boxed in by credits and paywalls, try EmailScout. It's built for finding business emails fast, saving contacts as you work, and helping you build outreach lists without slowing down your day.